virag/banko-ai-assistant
AI Banking Assistant using Agentic AI, LangChain CockroachDB, and real-time vector search
6.7K
virag/banko-ai-assistant repository overview


Banko AI Assistant
A demo banking assistant that combines vector RAG, a LangGraph multi-agent pipeline, and runtime-switchable LLM providers — all backed by a single CockroachDB cluster.
What it can do
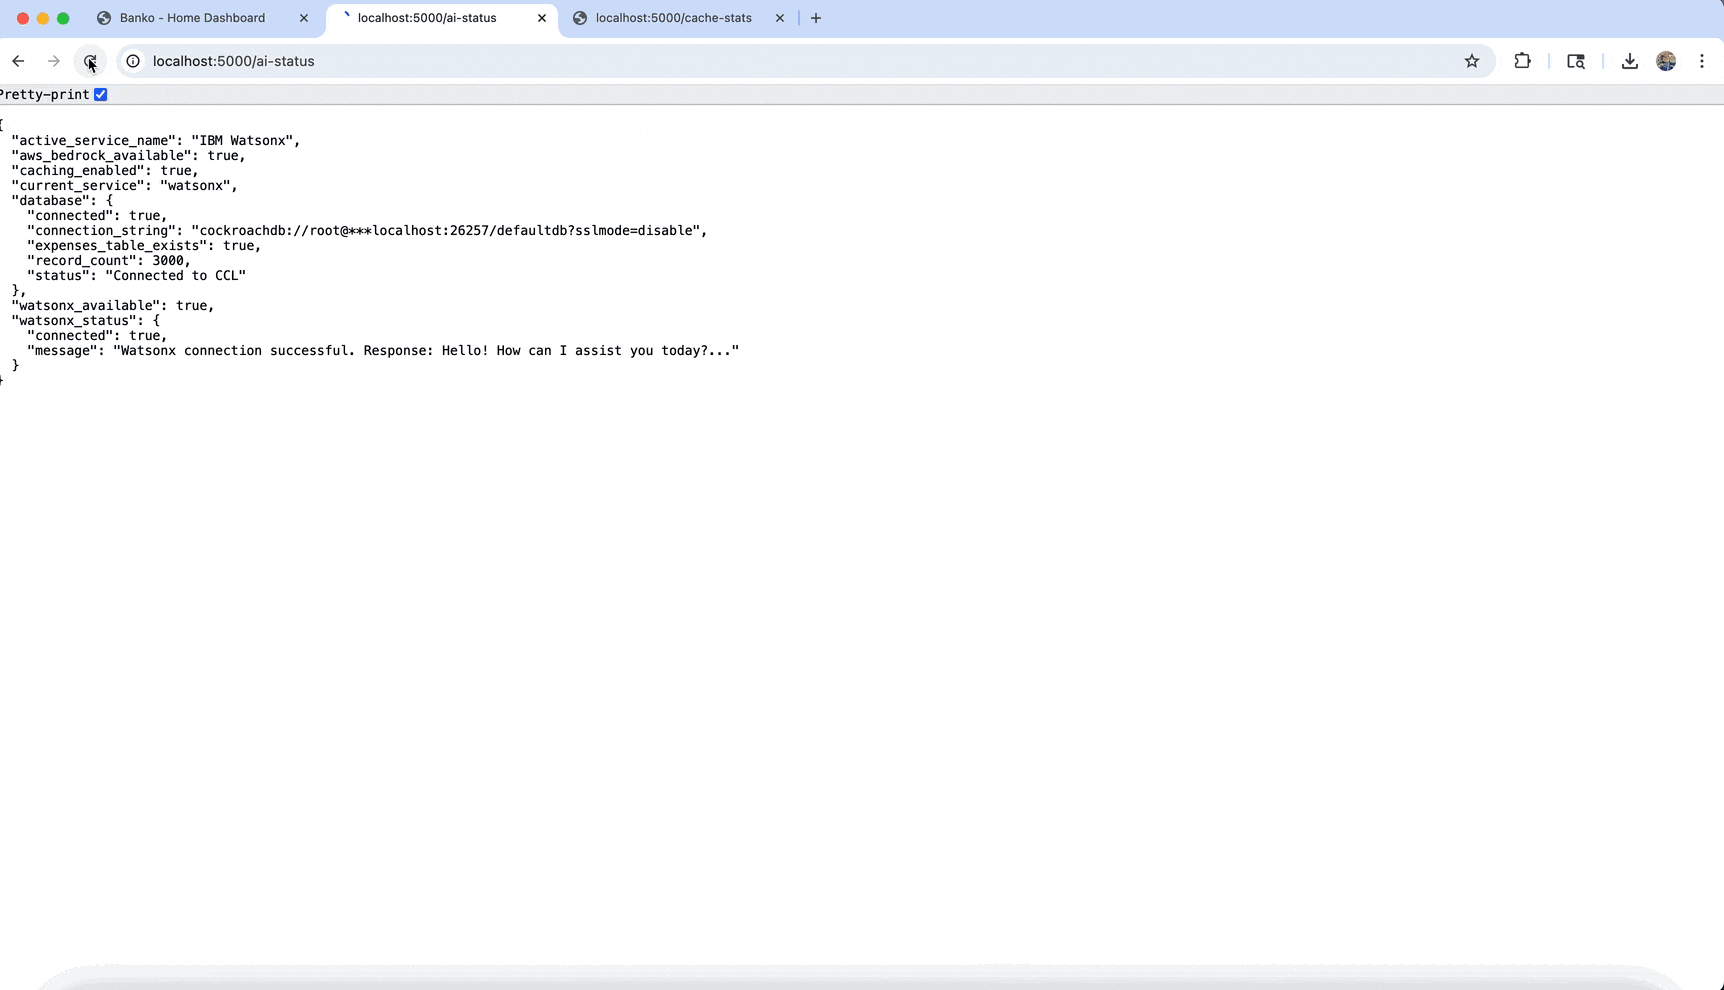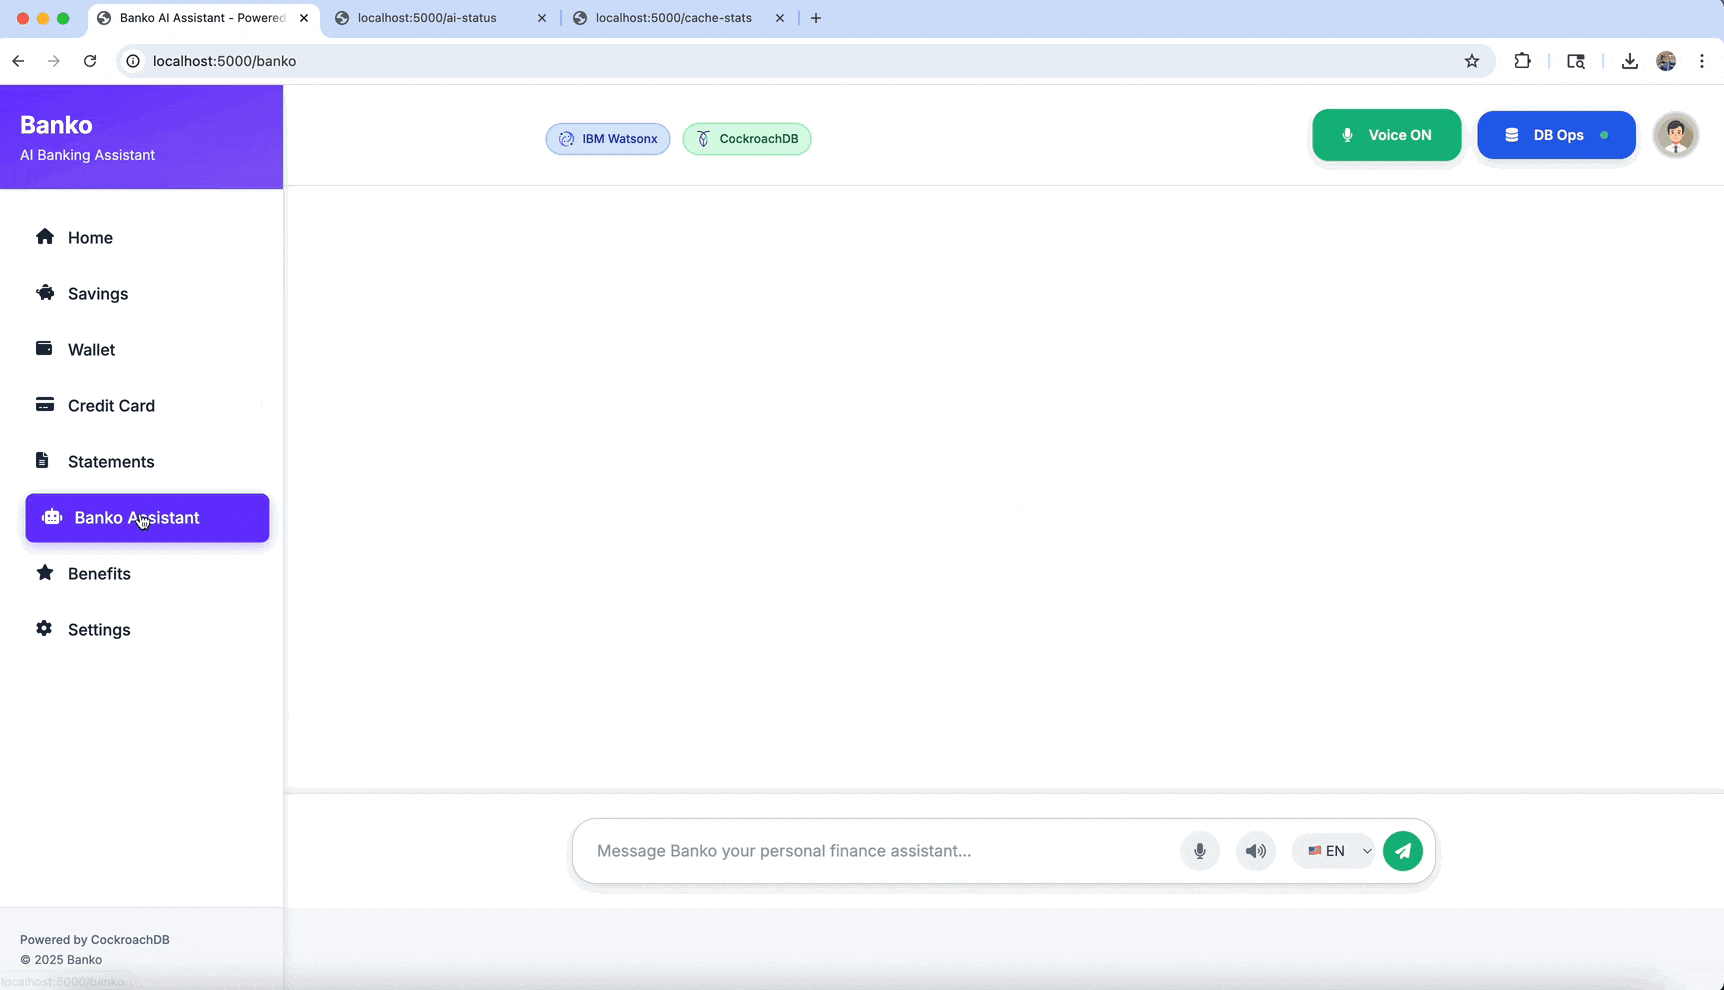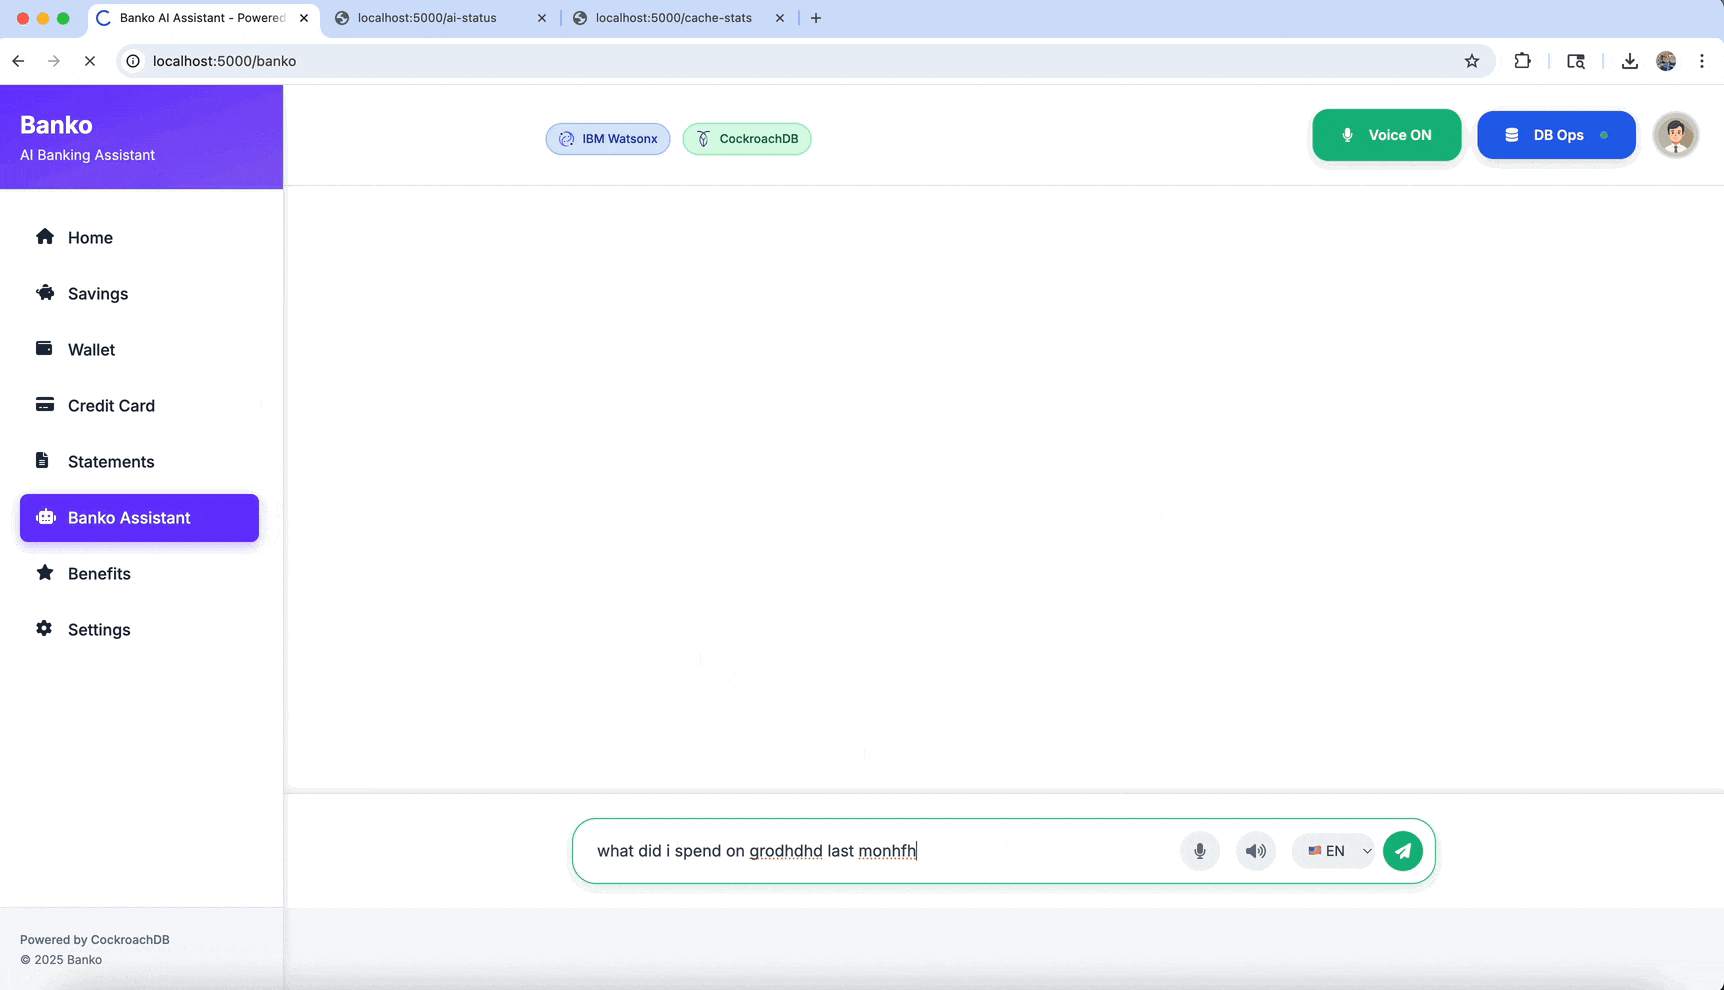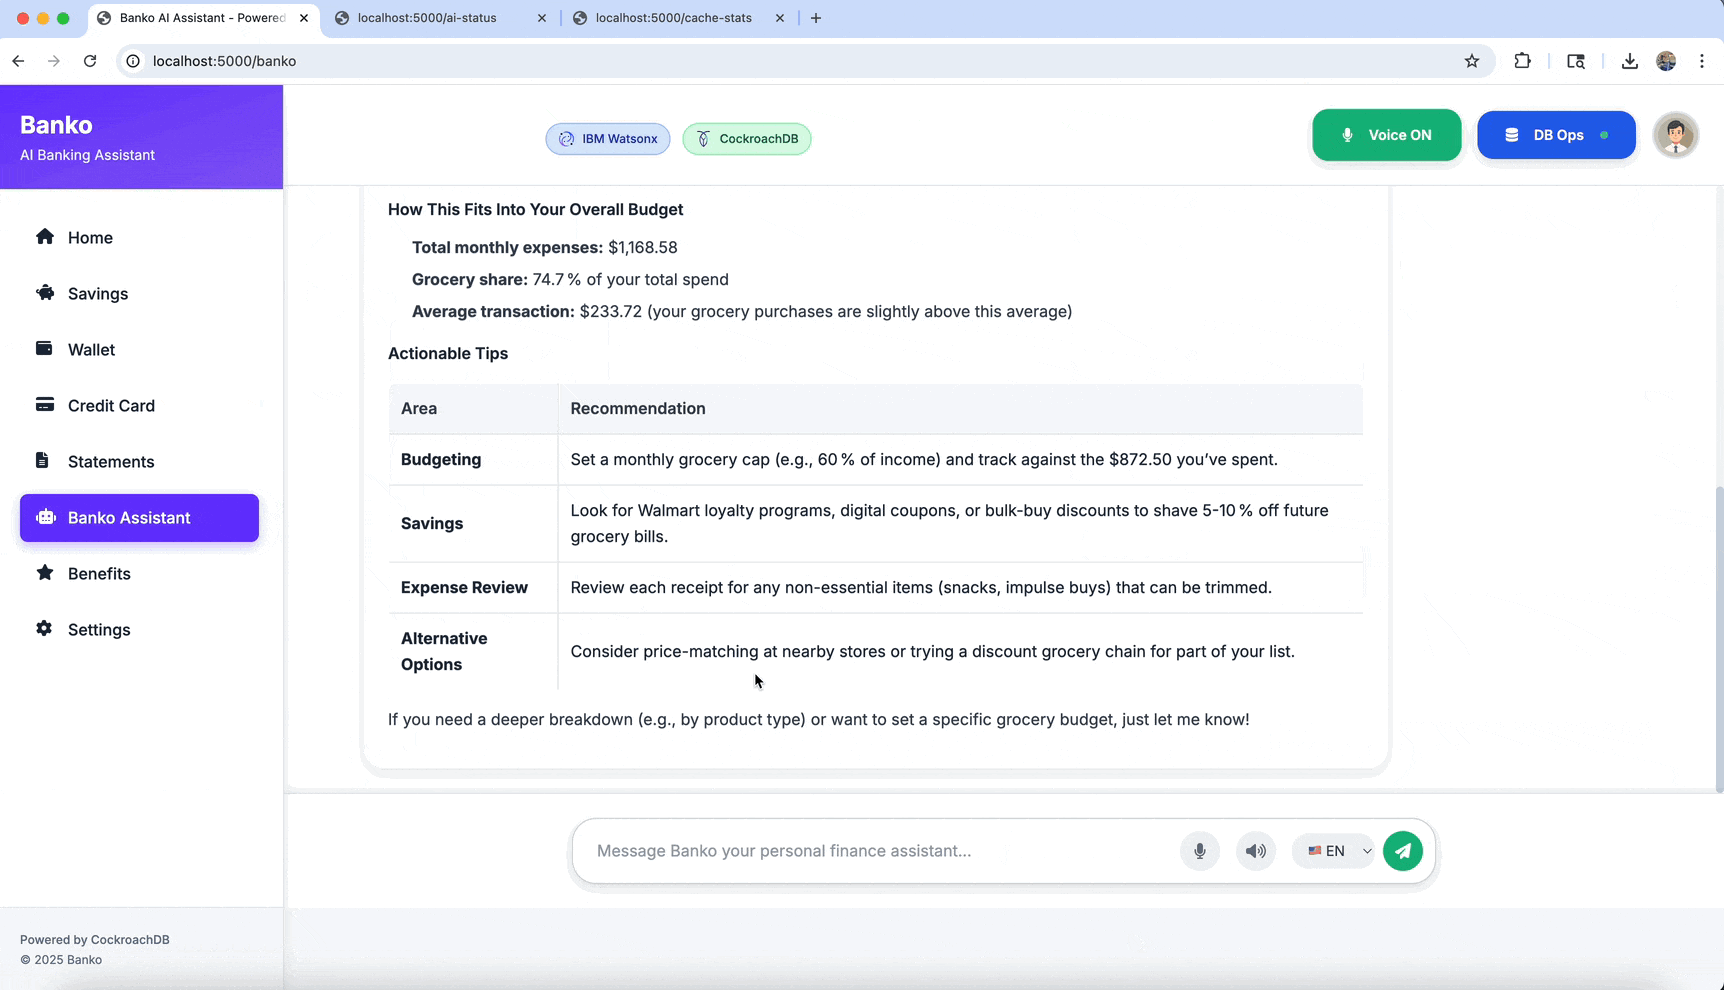
- Ask in natural language — "what did I spend on dining last month?", "show me anything unusual" — answers come from vector search over your expenses plus an LLM-generated summary.
- Upload a receipt — image or PDF goes through an OCR + agent pipeline
(
Receipt → Fraud → Budget) that extracts items, flags duplicates, and reports budget impact, with each agent step durably checkpointed. - Multi-provider LLM — watsonx (default), OpenAI, AWS Bedrock, or
Google Gemini. The provider is chosen at startup via
AI_SERVICE; within a running app you can swap models inside the active provider from Settings (model lists come from each provider's API, not a hardcoded enum). Switching providers requires a restart with the new env value. - See agents work in real time — the dashboard streams actual agent state from the backend (no canned activity).
- Persistent chat — conversations survive restarts via
CockroachDBChatMessageHistory. - Three-layer semantic cache — query / embedding / vector-search caches with tunable similarity thresholds.
How it works
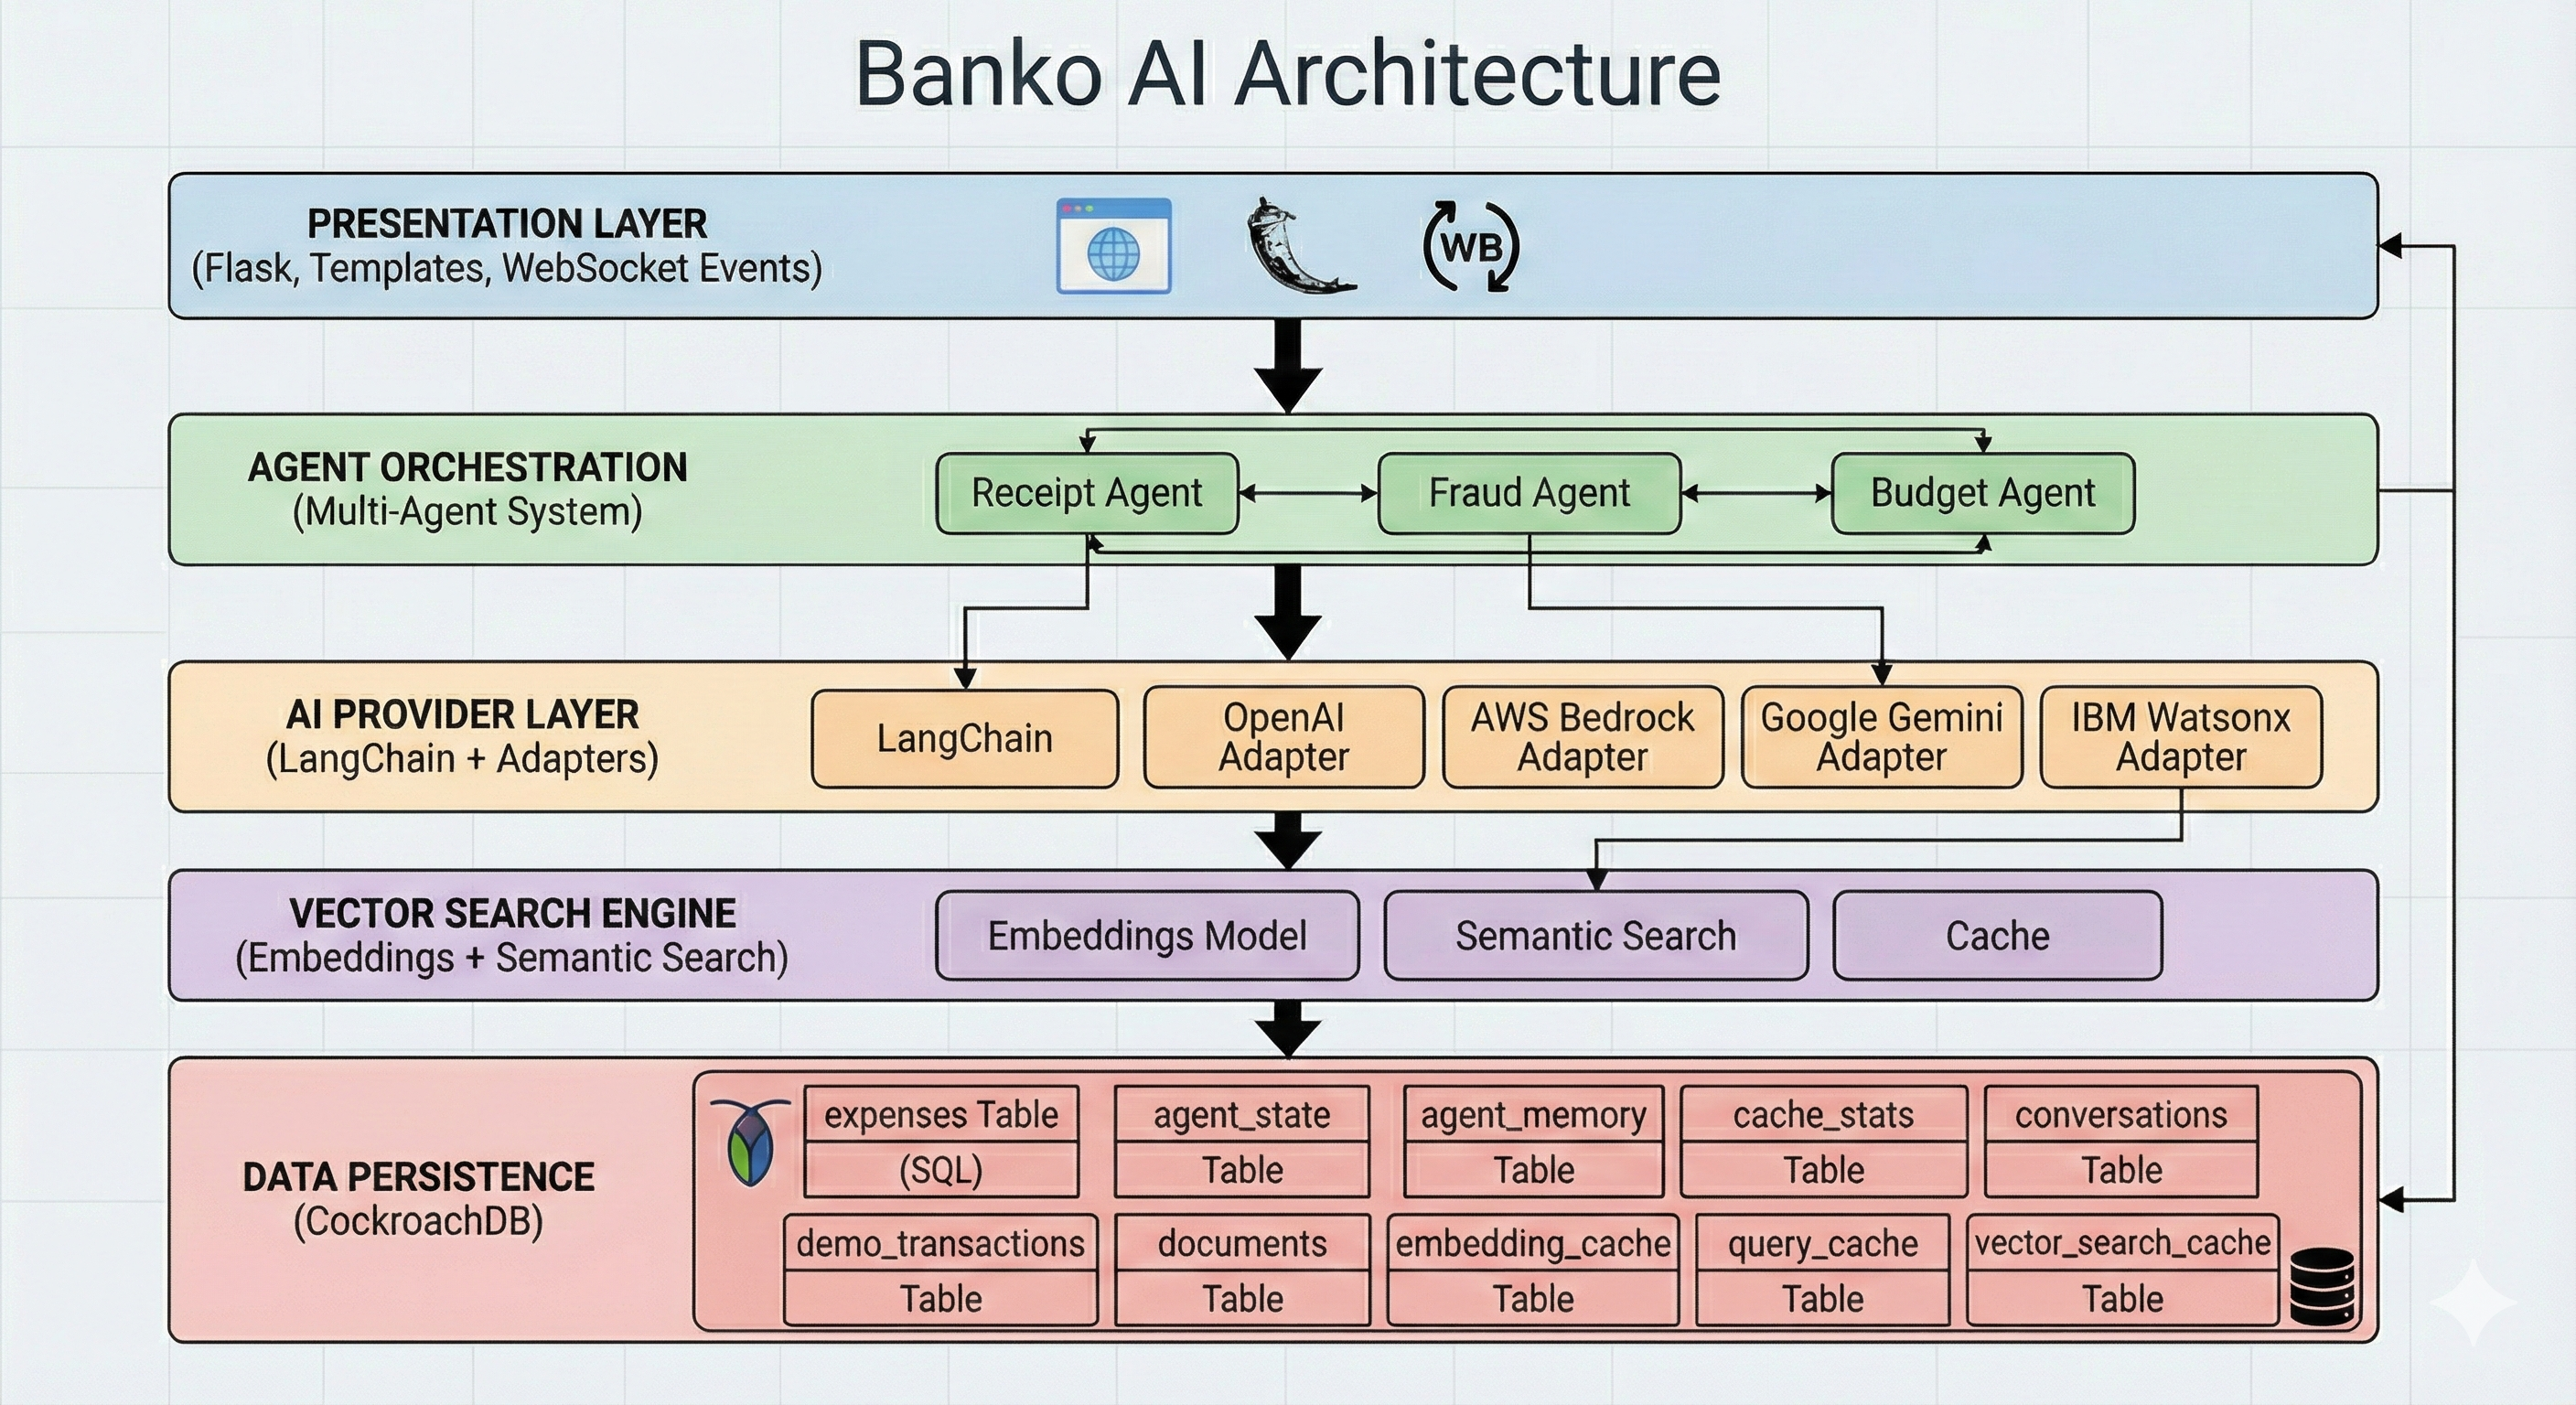
Five layers, one database:
| Layer | What it does | Where |
|---|---|---|
| Web | Flask + SocketIO UI, REST API, real-time agent status | banko_ai/web/ |
| Agents | LangGraph pipeline (Receipt → Fraud → Budget), checkpointed by CockroachDBSaver for crash recovery and replay | banko_ai/agents/ |
| AI providers | One abstraction over watsonx, OpenAI, Bedrock, Gemini — all LLM calls go through it | banko_ai/ai_providers/ |
| Vector search | CockroachDBVectorStore with C-SPANN cosine indexes, 384-dim all-MiniLM-L6-v2 embeddings (local, no API key) | banko_ai/vector_search/ |
| Persistence | CockroachDB stores SQL rows, vectors, and agent state in one cluster | banko_ai/utils/ |
All CockroachDB-specific pieces come from
langchain-cockroachdb:
CockroachDBEngine (psycopg3 pool), CockroachDBVectorStore,
CockroachDBChatMessageHistory, and CockroachDBSaver.
Run it
Prerequisites
- Python 3.10+ (3.12 recommended)
- CockroachDB v25.4.0+ (vector indexes are GA)
- An API key for at least one provider (watsonx, OpenAI, AWS, or Gemini), or a local model through Ollama (no key, no internet)
Install
pip install banko-ai-assistant            # PyPI
# or
docker-compose up -d                      # Docker
# or
git clone https://github.com/cockroachlabs-field/banko-ai-assistant
cd banko-ai-assistant
uv pip install -e ".[dev]"                # local development
Start CockroachDB
brew install cockroachdb/tap/cockroach    # macOS
cockroach start-single-node --insecure \
  --store=./cockroach-data \
  --listen-addr=localhost:26257 \
  --http-addr=localhost:8080 --background
Start the app
export AI_SERVICE=watsonx                 # or openai, aws, gemini
export WATSONX_API_KEY=...
export WATSONX_PROJECT_ID=...
export DATABASE_URL="cockroachdb://root@localhost:26257/defaultdb?sslmode=disable"

banko-ai run                              # port 5000, generates 5000 sample records on first start
banko-ai run --port 5001                  # custom port (macOS AirPlay grabs 5000)
banko-ai run --no-data                    # skip the sample-data generator
Open http://localhost:5000.
Sign up and it's yours
The first visit asks for a username. New names pick a spending style (diner, subscriber, saver, balanced) and get a seeded history in that style, embeddings included; returning names land straight back in their own data, and the Coach greets new users with a real nudge within seconds. Everything on screen is scoped to that identity: SQL aggregations filter by your user id, vector search runs through the per-user vector index, and the header shows who is signed in. Questions that ask for totals or counts ("how much did I spend on restaurants in the past 60 days?") are answered by SQL directly, so the figures are exact and identical no matter which AI provider is active; the model adds the narrative and suggestions around them. Every answer wears a badge with the real database time, and an expandable panel shows the actual EXPLAIN ANALYZE that produced it.
On a multi-region cluster the same app goes region aware with no extra
configuration: signup offers a home region (detected live from the
cluster), rows are pinned to it via REGIONAL BY ROW, reads prune to the
user's partition, and the answer badge names the regions that actually
served each query. Kill a region and the badge visibly moves to the
survivors while answers keep flowing. Single-region deployments see
none of this; nothing fake is ever rendered. The legacy personas
(maya, sam, riley) still exist for existing databases, and
banko-ai clear-demo-users resets a demo machine while keeping them.
banko-ai --help lists the rest (generate-data, clear-data, status,
search, etc.). The first run creates the schema (expense, agent, cache,
checkpoint tables), generates sample data with embeddings, and initializes
the selected provider.
Run it offline (airgap)
The whole stack runs without internet: embeddings are computed locally, and the LLM is a local model served by Ollama. Run the preload script once while online (it caches both the Ollama model and the embedding model into named volumes), then start the stack with the network off:
scripts/airgap/preload-models.sh                    # once, while online
docker compose -f docker-compose.airgap.yml up -d   # works offline
Default model is granite3.3:8b (override with OLLAMA_MODEL). For a
non-Docker setup, ollama serve plus AI_SERVICE=ollama banko-ai run
does the same thing. Any OpenAI-compatible endpoint also works via
OPENAI_BASE_URL with AI_SERVICE=openai.
Configuration
The important knobs:
| Variable | Description | Default |
|---|---|---|
DATABASE_URL | CockroachDB connection string | cockroachdb://root@localhost:26257/defaultdb?sslmode=disable |
AI_SERVICE | watsonx, openai, aws, or gemini | watsonx |
SECRET_KEY | Flask session key (auto-generated in dev) | random |
Provider keys depend on what you pick:
# IBM watsonx (default)
WATSONX_API_KEY=...   WATSONX_PROJECT_ID=...

# OpenAI
OPENAI_API_KEY=...

# AWS Bedrock — note AI_SERVICE=aws, not bedrock
AWS_ACCESS_KEY_ID=... AWS_SECRET_ACCESS_KEY=... AWS_REGION=us-east-1

# Google Gemini (Vertex AI)
GOOGLE_APPLICATION_CREDENTIALS=path/to/sa.json   GOOGLE_PROJECT_ID=...
# or the Generative AI API
GOOGLE_API_KEY=...
Override model lists with WATSONX_MODELS, OPENAI_MODELS, AWS_MODELS,
GEMINI_MODELS (comma-separated). Cache, fraud, and pool tuning live in
banko_ai/config/ (CACHE_SIMILARITY_THRESHOLD, CACHE_TTL_HOURS,
FRAUD_DUPLICATE_WINDOW_DAYS, DB_POOL_SIZE, …).
API
| Endpoint | Method | Purpose |
|---|---|---|
/api/health | GET | DB + AI status |
/api/ai-providers | GET | List providers |
/api/models | GET / POST | List or switch models |
/api/search | POST | Vector search |
/api/rag | POST | RAG-based Q&A |
/api/upload-receipt | POST | Run a receipt through the agent pipeline |
/api/agents/status | GET | Agent dashboard data |
/api/chat-history/<id> | GET / DELETE | Persistent chat per session |
Full list with examples in docs/API.md. Quick check:
curl -X POST http://localhost:5000/api/rag \
  -H "Content-Type: application/json" \
  -d '{"query": "What are my biggest expenses this month?"}'
The Spending Coach (streaming + agentic)
Everything above waits for a question. The Coach reacts to events: a
spending signal arrives, an agent investigates with real budget and
transaction tools, and a nudge appears live on the /coach tab, for
example "you've used 82% of your dining budget with 9 days left." Signals
and nudges live in CockroachDB with row-level TTLs, and the agent's
conversation state checkpoints there too.
Kick it off the quick way, by posting a synthetic signal at the webhook:
export CDC_WEBHOOK_HMAC_SECRET=dev-only-secret   # same value as the app
uv run python scripts/coach/mock_signals.py --type=budget_threshold
# also: --type=anomaly, --type=recurring_drift
Or run the real thing: CockroachDB changefeeds streaming through Debezium
and Kafka into the app. One script brings up Kafka, Kafka Connect, and the
Debezium CockroachDB connector, then registers a source on the
spending_signals table:
scripts/coach/cdc-demo/run-cdc-demo.sh
# then run the app with the Kafka transport on:
COACH_KAFKA_ENABLED=true KAFKA_BOOTSTRAP_SERVERS=localhost:29092 \
  AI_SERVICE=watsonx banko-ai run
With that stack up, sending a change event is just SQL. Insert a row and CockroachDB streams it to the Coach, no webhook involved:
INSERT INTO spending_signals
  (user_id, signal_type, severity, payload, idempotency_key)
VALUES
  ('00000000-0000-0000-0000-0000000000a1', 'budget_threshold', 'warn',
   '{"category": "dining", "pct_used": 0.82, "monthly_budget": 400.0,
     "spent_so_far": 328.0, "days_remaining": 9}',
   'demo:' || gen_random_uuid()::STRING);
Watch /coach while you run it. To verify the whole path automatically:
uv run python scripts/coach/assert_nudges.py             # webhook transport
uv run python scripts/coach/assert_nudges.py --via sql   # the CDC pipeline
The producer contract (payload shapes, idempotency, both transports) is in PIPELINE_CONTRACT.md.
Where the data plane comes from
This repo is the agent side. A companion repo,
viragtripathi/cockroachdb-watsonx-data-pipeline,
streams CockroachDB CDC events into Apache Iceberg on IBM watsonx.data
(both via webhook and Debezium → Kafka). Neither repo requires the other —
this app works against a local CockroachDB with its own sample data — but
the two together demo the end-to-end transactional + lakehouse path.
Testing
python -m pytest tests/ -v                # all tests
ruff check banko_ai/                      # lint
Integration tests need a populated CockroachDB; they're skipped in CI when the DB isn't available.
Troubleshooting
- CockroachDB version — must be v25.4.0+ for vector indexes
(
cockroach version). - DB connection error — confirm the single-node command above is
running, then
cockroach sql --insecure --execute "SHOW TABLES;". - AI provider issues — confirm keys are exported, then hit
/api/health. For watsonx,/diagnostics/watsonxhas connection details. - Port 5000 in use (macOS) — AirPlay Receiver claims port 5000.
Either disable it in System Settings → AirDrop & Handoff, or run
banko-ai run --port 5001.
License
MIT
Tag summary
Content type
Image
Digest
sha256:9ce546553…
Size
899.3 MB
Last updated
26 days ago
docker pull virag/banko-ai-assistant